Moji - OCR (early preview)

Moji OCR
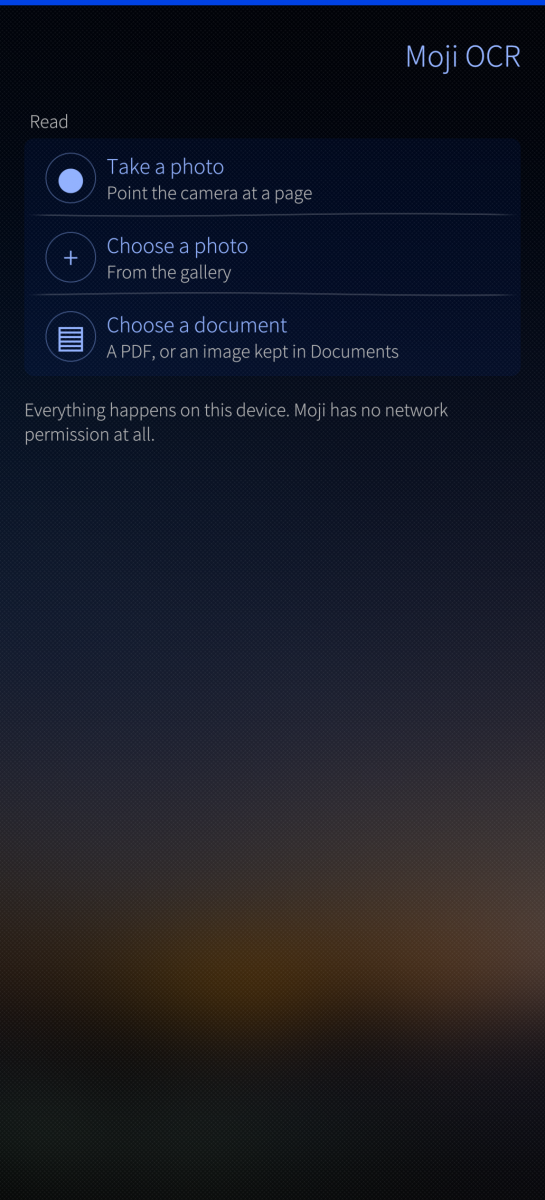
Read text from photos and PDFs, entirely on the device. And yes before you continue reading, the app was made by a human developer with the help of an LLM.
WHAT TO EXPECT: PLEASE READ THIS FIRST
It will not read everything perfectly. Expect to correct words.
Recognition that runs entirely on a phone, with no server behind it, is not the same thing as recognition by Google or Apple. They have research teams and data centres. This is one person, and a recogniser small enough to ship inside the package along with thirty languages.
On a clean photograph of a printed page it gets roughly 85–92% of the words right. On a photograph of a street sign at night it does badly.
That is a limit of the approach, not a setting you can turn up.
It is a deliberate trade. Nothing you photograph ever leaves the phone and not because a privacy policy says so. The app has no network permission at all, so the Sailfish sandbox refuses every outbound connection whether the code deserves that trust or not.
So Moji is built for being wrong sometimes:
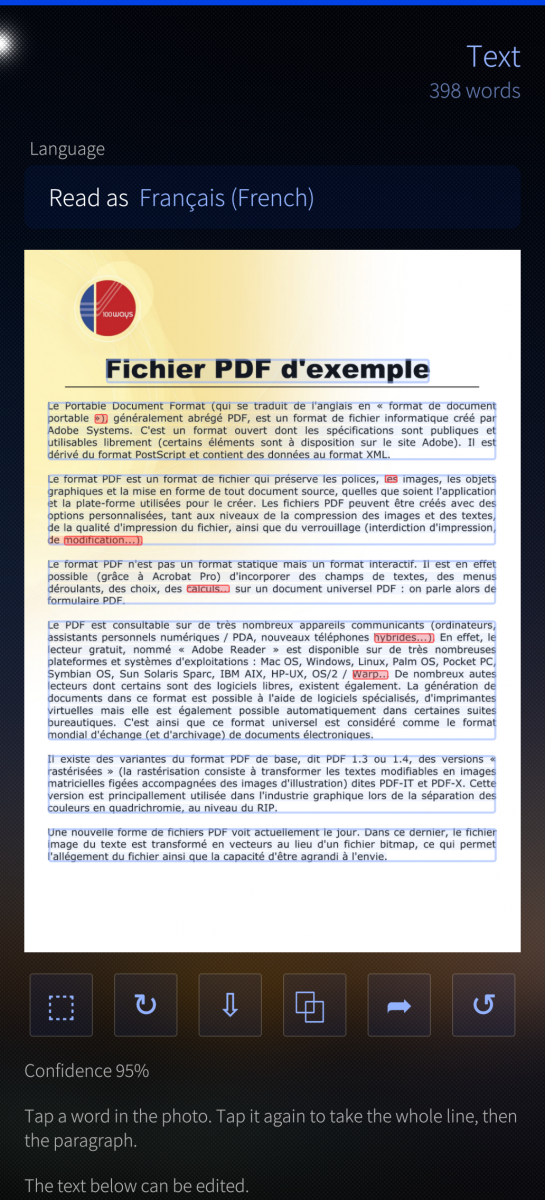
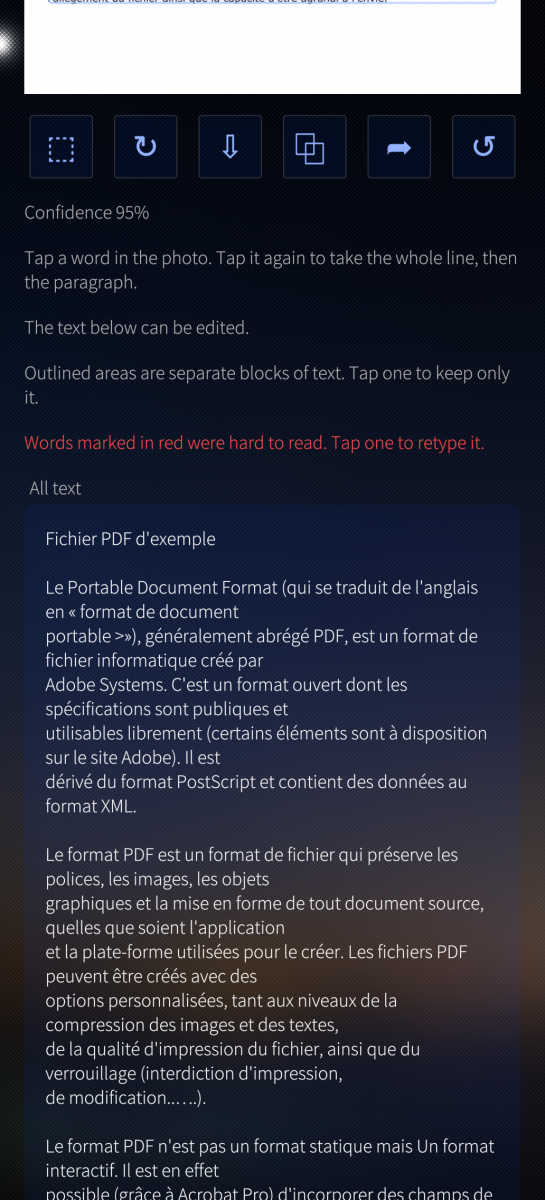
- Words it doubts are tinted. Tap one and retype it, the correction follows everywhere the original went.
- Account numbers are checksums: IBANs by mod-97, card numbers by Luhn, ISBNs and passport codes by theirs. OCR confuses 8 with B, which is exactly what a checksum is for.
- The confidence is shown, per page and per word. You are meant to read the result, not tr
THE REST
- Tap a word, tap again to widen, the selection grows to the line, the paragraph, then the block the recogniser actually found.
- Private numbers painted out, flattened into the pixels of a saved copy, not an overlay a viewer can switch back on.
- Reads PDFs as well as photographs.
- Exports the photo together with its text. Shares to any app.
- Reads the page whichever way up it was photographed.
- A torch, for signs at night.
Thirty recognition languages, all in the package, including Arabic, Hebrew, Chinese, Japanese, Korean, Hindi, Thai and Vietnamese. These are Tesseract's own models, unmodified, and I could only test a few of them. So if some of them read badly, don't hesitate to tell me.
I'd love to improve the app, and I'd rather spend time improving it than arguing online :)
Interface in English and French.
EARLY PREVIEW. Tested on one device by one person. Please report what
breaks, that is what it is here for.
Source: github.com/nicosouv/harbour-moji
Code is MIT. The binary is GPLv2+, because it links Poppler to render PDF pages.
Screenshots:
Category:
Keywords:
Application versions:
| Attachment | Size | Date |
|---|---|---|
 harbour-moji-0.1.19-1.armv7hl.rpm | 49.34 MB | 16/09/2026 - 00:08 |
| harbour-moji-0.1.19-1.aarch64.rpm | 49.74 MB | 16/09/2026 - 00:08 |
Recent comments